Automated Style Enforcement for Content Teams
Enforce brand voice at creation, not in review.
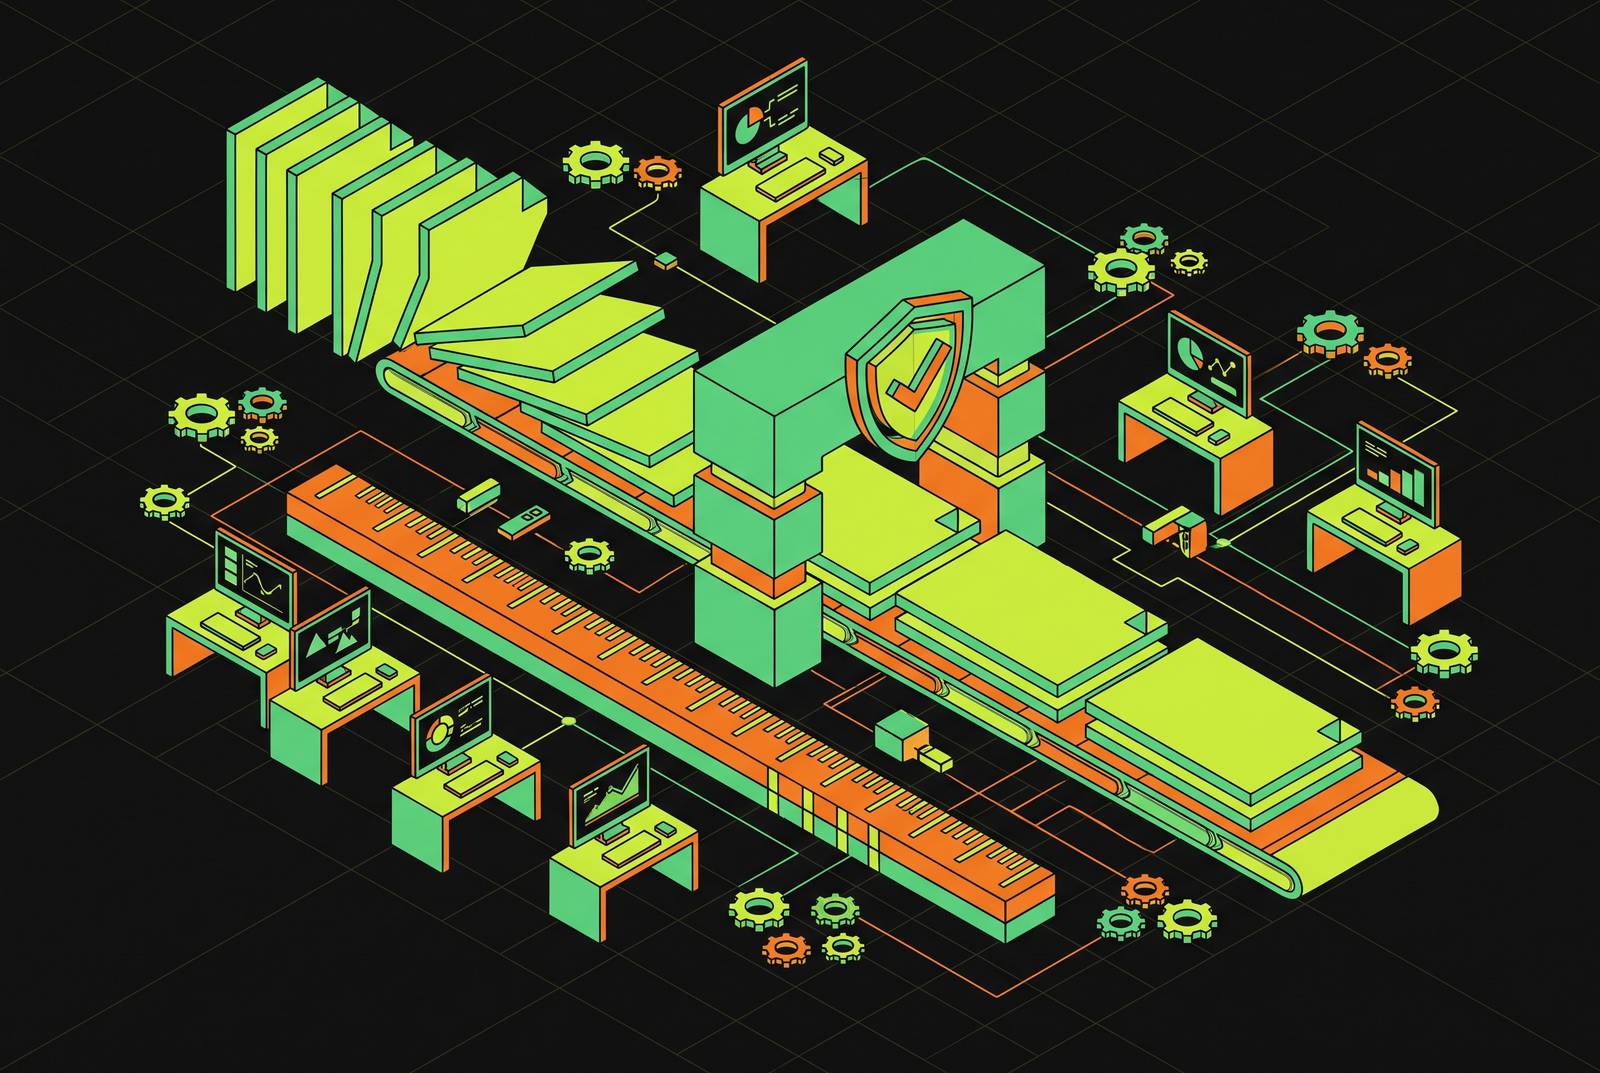
Content teams have learned, often the hard way, that a style guide means little if nobody enforces it at the point of creation. Automated enforcement only holds when it is built into the production pipeline as a structural control, not applied after the fact as a corrective editing pass. The distinction determines whether a brand's voice remains its own or quietly dissolves into the model's.
Why style enforcement belongs in the pipeline, not after it
The predictable failure looks like this: a team adopts several AI writing tools, each with its own defaults, and no shared enforcement mechanism connects them. Brand voice becomes whatever the model defaults to, not what the brand intends. When enforcement happens only at the end of the chain, consistency is structurally impossible.
Practitioners have a name for the condition: brand voice drift. The architectural distinction that matters is where governance runs. At the generation layer, it flags and prevents non-compliant output before it reaches review. At the detection layer, it catches problems after the fact and sends them back. One is a control inside the pipeline. The other is a correction outside it.
How brand voice drift actually happens — the structural mechanics
Brand voice drift is not the result of bad writing. It is the predictable output of a system where multiple people and AI tools produce content simultaneously without documented standards or automated enforcement binding them together. When content teams scale without operational infrastructure, several failure modes show up consistently.
When writers, freelancers, and AI tools produce content at the same time, brand voice becomes whoever spoke loudest that week. Documented standards without enforcement mechanisms leave consistency aspirational at best. Quality regression is the second mode: speed pressure compresses human review, AI-generated content ships with minimal editing, and the result is generic, undifferentiated output that damages credibility. The specific causes vary, but the pattern is consistent: the bottleneck moves from creation to approval, volume gains evaporate, and the editorial function becomes a rubber stamp.
The single-model problem compounds every one of these failures. A team running all content through one LLM is not simply getting one voice. It is getting that model's trained defaults, shared with every other team using the same model. The operational conclusion follows: the best LLM is rarely a single model. What is missing is a governing layer that enforces standards across whatever models a team uses.
Why single-model output is structurally detectable — and what that means for brand voice
A single LLM leaves a detectable fingerprint in its output. The patterns show up in word choice, transitions, and semantic structure, and they are consistent enough for detection systems to identify as model-specific. Modern detection systems do not output a single percentage. They produce sentence- or paragraph-level risk scores, feature attributions covering entropy and burstiness, and an explanation of which signals drove the decision.
The watermarking dimension adds regulatory urgency. From August 2026, EU AI Act Article 50 requires AI-generated content to be labeled. On 5 October 2026, OpenAI announced it would roll out watermarks for its models initially in the EU under a strategy called textGrain, with a detection API for approved researchers and expert organizations. These are cooperative watermarks, embedded in the token selection process itself rather than added as metadata. Research responses include PostMark, a robust blackbox watermark. DualGuard defends against paraphrase and spoofing simultaneously. And semantic watermarks embed the signature in meaning rather than token choice.
For brand voice, the implication is direct. The brand voice, in other words, is not the brand's. It is the model's.
The regulatory layer that makes enforcement mandatory, not optional
The EU AI Act, in force from August 2026, converts automated style and compliance enforcement from a best practice into a documented legal requirement for teams producing AI-assisted content at scale. Article 50 requires that AI-generated content be labeled. The labeling obligation entered into force on 2 August 2026, with a transitional period until 2 December 2026 for the machine-readable marking duty on systems already on the market. Article 4, the AI literacy obligation, has applied since February 2025: every company deploying AI systems must demonstrate that the people involved have sufficient AI competence.
ISO/IEC 42001, the world's first standard for AI management systems, defines 38 controls across nine areas including risk assessment, data quality, and continuous improvement. For content teams, it specifically requires traceability: who executed which prompt, with which model, in which version, and when, and how the output was reviewed and approved. The structural difference between classic and AI content governance is not gradual. AI content governance extends this with a control layer that classic governance was never built for: prompt governance, LLM monitoring, automated compliance checks, and audit trails for machine-generated content. Managing AI-generated content with the same approval processes as editorial text misses the fact that the machine neither knows brand guidelines nor respects regulatory boundaries unless both are technically enforced.
What built-in enforcement actually looks like — the architecture of a style control layer
Effective style enforcement requires a deliberate harness: scaffolding that assembles the agent, and a runtime layer that enforces quality gates. It is not a single model with a long system prompt. A stateless, reactive LLM is not a production system. The harness must assemble the agent before the first prompt runs, with system prompts, tool schemas, and a subagent registry in place, then orchestrate tool dispatch, context management, and style enforcement at runtime.
The key leverage point is structural: free-form prose output should be constrained by a structured completion report schema. Without the schema, every downstream quality gate must re-extract facts from prose. With it, quality gates run as deterministic checks. Multi-model architectures can be organized hierarchically, such as concurrent sessions composed of multiple specialized sub-agents, each executing typed workflows that independently bind to a user-configured LLM. That structure allows fine-grained model selection, so cost, latency, and capability trade-offs can be optimized per workflow stage rather than fixed across the whole pipeline.
Most organizations work through a three-layer progression. Prompts come first: documented, shared, versioned. Retrieval, the second layer, augments generation with curated on-brand content. Explicit voice descriptor tagging, such as "playful," "technical," or "luxury," in the retrieval corpus is required to close that gap. For long-form corpus ingestion, a minimum of roughly 15,000 words of highly polished, representative text is necessary.
Cost is a design constraint, not an afterthought. For multi-turn sessions, partitioning system prompts into stable and dynamic parts, using cache-control headers in Anthropic's API for the stable portion, yields substantial cost reduction on the cached content across sessions. That is what makes recursive enforcement architectures economically viable at scale.
Adversarial multi-model review as a structural fix for voice convergence
Routing content through a single model and refining it with prompts is a prompting strategy, not an infrastructure strategy. What actually moves prose away from any single model's detectable defaults is distributing generation and critique across multiple models that draft, review, and contest each other's output. The practical benefit is parallelism. Task-specific model specialization is real: comparative testing confirms that different models have different strengths for different content tasks.
The adversarial dimension is what converts a pipeline into a quality gate. A multi-detector adversarial council avoids this failure mode because no single detector is the target. Each model brings different priors, and that diversity makes it harder to converge on any one model's defaults.
Recursion is the mechanism, not the overhead. Iterating through multiple rounds of adversarial critique until output converges on a quality threshold follows the same logic that makes test-driven development reliable. The iteration is the quality control, not a cost to be minimized.
Where commercial tools sit in this stack — and what they actually enforce
Most commercial style enforcement tools operate at the detection and post-hoc review layer, not at the generation layer. They are useful for compliance documentation and for catching obvious violations, but they do not prevent brand voice drift from occurring in the first place. Understanding what each tool actually enforces is the prerequisite for buying the right one.
Copyleaks addresses the compliance and detection layer directly. Sight AI takes a different angle. Its Autopilot Mode handles publication at scale with minimal manual oversight, while Sentiment Analysis and Prompt Tracking identifies inaccurate, harmful, or missing brand representations in AI model outputs. The platform addresses a compliance challenge most other tools miss: what AI answer engines are saying about the brand, not just what the team is publishing.
At the template and approval layer, Marq operates through Brand Guardian, which reviews content in real time as it is created against brand rules set by team, location, or brand. Templafy provides document-level AI compliance inside Microsoft Office, with smart document automation, dynamic fields, auto-populated disclaimers, and conditional logic for correct content based on document type or user role. CHILI Publish offers developer-led AI rendering for high-volume print and digital production, with the Smart Template editor GraFx Studio for complex template logic. Adobe Express serves teams already in the Adobe ecosystem, with Firefly AI for content-aware editing and Creative Cloud Libraries that sync brand assets automatically, but at a medium governance level with no locked fields or approval workflows.
Seven evaluation criteria for choosing where enforcement lives in your stack
The right enforcement tool is determined by where in the pipeline the failure mode occurs. A team with a compliance documentation problem needs different infrastructure than a team with a generation-layer voice drift problem. Conflating the two leads to buying tools that address the wrong layer.
Seven evaluation dimensions, adapted from practitioner governance frameworks, clarify the choice. First, enforcement layer: does the tool operate at detection, template and approval, or generation? Second, prompt governance and audit trail: can the tool log which prompt was executed, with which model, in which version, and when, and is that log exportable for compliance documentation under ISO/IEC 42001 traceability requirements? Fourth, brand corpus ingestion and post-trainability: can the tool be trained on the team's own writing corpus so that its style defaults reflect the brand's actual voice, and is fine-tuning available or only prompting? Fifth, API and pipeline integration depth: can enforcement be reached by an agent through an API without requiring a human to open a UI, and does the tool expose composable primitives rather than requiring a monolithic platform? Sixth, multi-model or single-model architecture: does the tool route through a single model, inheriting its fingerprint and defaults, or across multiple models, which distributes and averages away model-specific patterns? Seventh, regulatory alignment: does the tool produce the documentation required for EU AI Act Article 50 and ISO/IEC 42001 compliance, and does it surface that documentation in a format auditors can use?
The prioritization logic follows directly. Teams with regulatory exposure, such as financial services, healthcare, or EU-operating companies, should weight prompt governance, audit trail, and regulatory alignment highest. Teams with compliance documentation gaps should weight audit trail and LLM monitoring. Most teams will need tools from more than one layer, which argues for composable primitives over monolithic suites.
Building the enforcement layer incrementally — a sequenced rollout for content teams
The biggest risk in building style enforcement infrastructure is treating it as a big-bang implementation. The teams that get it right build in layers, starting with the failure mode costing them the most, and instrument each layer before adding the next. The sequence mirrors the three-layer progression.
Layer 1 is a shared prompt library and style guide as code. Document brand voice rules in a format that can be version-controlled and referenced by prompts. This is the minimum viable governance layer and the prerequisite for everything above it. Layer 2 adds detection and audit integration. Place a detection-layer tool such as Originality.AI or Copyleaks into the publishing pipeline as an automated gate. This satisfies the immediate compliance documentation requirement under ISO/IEC 42001 and provides a baseline measurement of how much model-default content is currently going out. That measurement is the precondition for knowing what the generation layer needs to fix.
Layer 3 is retrieval with explicit voice tagging. Build or extend a RAG corpus with explicit voice descriptor tags to prevent tone drift on new content categories. This is where the operational hazard of semantic-only retrieval is eliminated. Layer 4 is generation-layer enforcement and adversarial review. Instrument the generation pipeline with a structured schema that makes quality gates deterministic, introduce adversarial multi-model review for high-stakes content, and evaluate post-training with PEFT on the brand corpus for environments where volume justifies the investment and roughly 15,000 words of polished representative text are available.
The instrumentation principle applies throughout. Each layer should produce measurable outputs: detection scores, audit logs, voice-consistency metrics. These feed back into the layer above them. The composability principle holds the same weight. Each layer is a primitive that can be wired into an existing stack. Enforcement is infrastructure. It is built, measured, and iterated the same way any other engineering system is.