Encoding Editorial Taste as Computable Quality Criteria
Editors' instincts become pass-or-fail tests that run on every draft.

AI content quality gates for content teams turn what editors want into tests that run before a piece is published and after each revision. A working system combines deterministic checks, calibrated model-based review, and explicit thresholds for passing, human review, or blocking release. Editorial taste becomes enforceable when teams name the properties of good writing and encode them as criteria.
Why editorial taste resists formalization — and why that resistance is an illusion
An editor says “this doesn't feel right,” then, when pressed, identifies something concrete. The subject is buried, the verb is weak, or the transition is a crutch. The editor’s first judgment sounds like instinct because years of practice have gone into that reaction. What feels holistic often resolves into observable properties of sentences.
Each reviewer uses a different mental model, and the feedback gives the drafter little to go on when revising. Under time pressure, even experienced editors apply their internal rules inconsistently. A preference confined to one person’s head cannot be audited, transferred, or enforced across a team. The terms of editorial taste have yet to be made explicit.
What single-model AI output reveals about unformalized taste
A model asked to research, structure, write, and optimize all at once must split its attention among goals that compete with each other. Without clear correctness criteria, prose that sounds right can meet the request even when it lacks depth, nuance, and voice. Fluency is not an adequate acceptance test. As generation progresses, context drift can pull the draft toward generic “web-English” rather than the specific voice requested in the prompt.
That flattening is visible in the text. Over-bulleting, em/en-dash overuse, repeated sentence openers, and habitual transitions such as “Additionally” and “Furthermore” are identifiable patterns. Buried verbs, uniform sentence rhythm, and term drift provide further evidence. These flaws can make marketing language that seems acceptable lose the very differences a brand voice is meant to convey.
Instead of asking for a draft that sounds less generic, the team can name the features that made this draft generic. Repeated openers call for a repetition check, while term drift calls for a judgment about whether the same concept retains the same name. The failure becomes a candidate for a test. That is the bridge from an editorial impression to an enforceable criterion.
How implicit preferences become named, testable properties
The first step is to collect approved and rejected writing from the team’s own corpus. Generic examples cannot establish what distinguishes that team’s voice. Approved passages show which choices reviewers accept, while rejected passages show where they draw the line. Both are necessary evidence. A collection of failures alone cannot show whether a proposed rule would also reject writing the team values.
The second step is to name the properties that distinguish approved examples from rejected ones. “This is flat” expresses a reaction but does not identify a repair. “The main verb appears after word fifteen” names an observable property, although the team must still establish whether that property explains its judgments. Another rejection might become “the opening sentence restates the headline verbatim.”
The third step is to turn the named property into a pass-or-fail condition. Sentence-opener repetition, transition frequency, heading case, and citation format can be checked deterministically. Vague claims, stress position, term drift, and citation discipline require semantic interpretation. A structural check can assess formatting, but judging whether a citation supports a claim requires more than matching a pattern.
The fourth step is to verify the rule against the corpus. It must catch what the editor would catch without rejecting approved examples. The agent-style project documentation describes structural rules derived from AI output logged across dozens of writing projects from 2022 to 2026, illustrating how observed patterns can become deterministic checks. Those checks belong in a linter or CLI, separate from semantic review, so enforcing heading case does not require a model call.
What a voice specification actually contains and how it gets built
A voice specification is the structured artifact that holds these conditions. It is not simply a prose style guide asking for writing that is confident, clear, or distinctive. A versioned file such as voice-spec.md gives those preferences an evaluable form. The senior editorial lead owns it. Every human or agent generating content uses it as the primary source of truth for the intended voice.
The file contains positive examples with annotations explaining why they passed and negative examples identifying the violations that caused rejection. Those examples are the basis for clear structural and semantic rules. A threshold definition states which scores or combinations of passes qualify output for production. Examples supply context that helps distinguish an intentional stylistic choice from a pattern that merely resembles one.
The corpus determines how specific the specification can become. A thin or generic collection produces rules that describe average acceptable writing. The proposed success test is concrete. Three independent drafters, using only the file and a system prompt derived from it, should produce consistently on-voice copy that passes a blind discrimination test.
Maintaining the file requires the same discipline as maintaining other correctness criteria. A rule change is logged, its reason is documented, and existing output can be evaluated against the new version. Version control makes that history inspectable.
How computable criteria fit into a multi-pass writing system
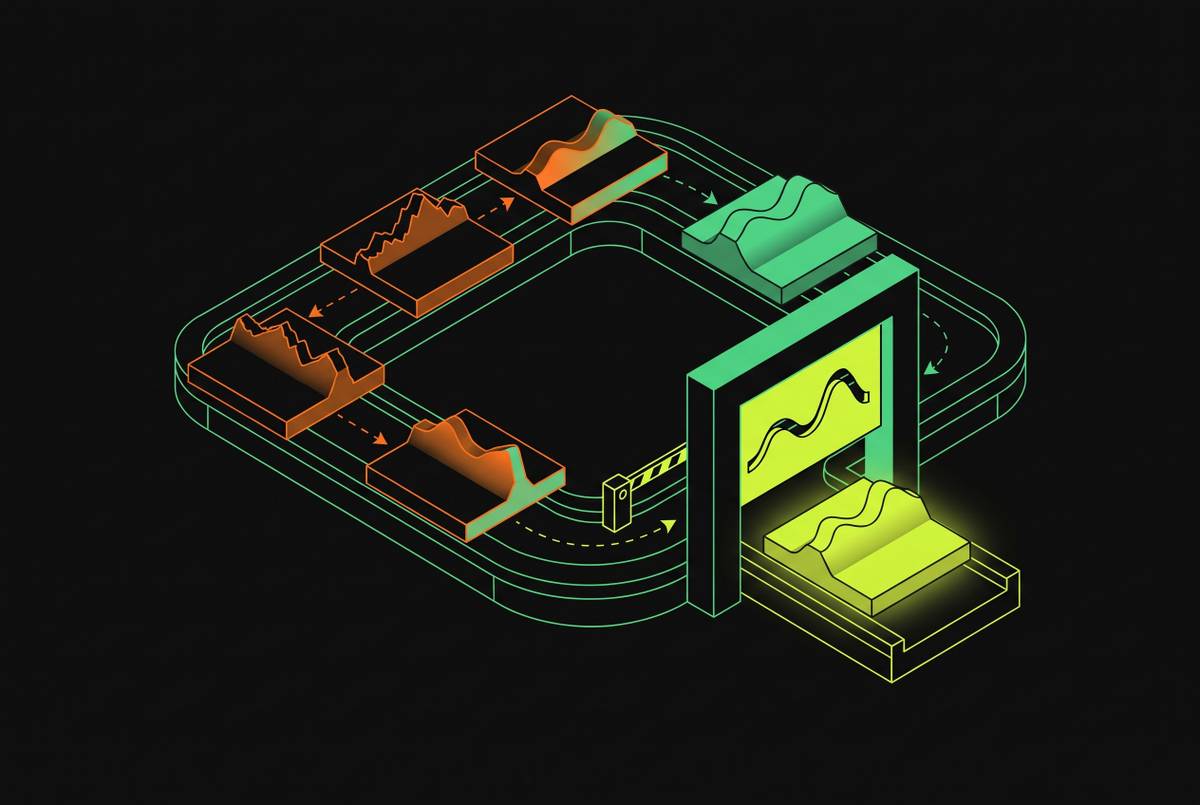
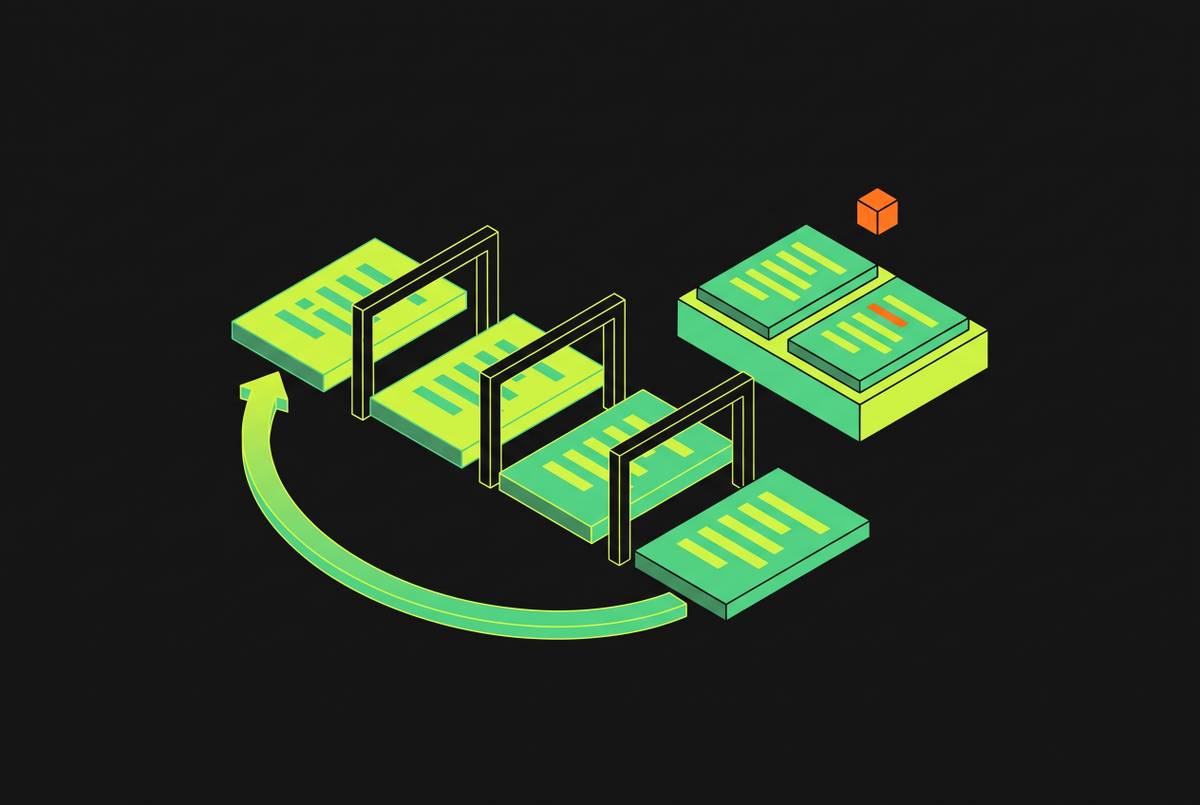
A quality check applied only at the end grades a finished draft. A criterion evaluated after every pass helps shape the draft itself. This difference determines the architecture. In a multi-agent system, a draft agent produces text, specialist reviewers evaluate it, and an orchestration layer returns specific findings for revision.
The review roles separate structural compliance, semantic quality, and voice fidelity. Structural review can use deterministic checks, while semantic and voice review need judgments based on the specification. Each review produces findings about particular violations. The orchestration layer sends those findings back to the draft agent so that a human is spared the work of fixing every sentence. Revision becomes part of the system’s work.
Disagreement between reviewers is useful evidence. When agents score the same passage differently, the conflict can expose ambiguity in the criterion. That ambiguity belongs in the next review of the specification. Likewise, repeated failure to converge on one criterion can indicate a miscalibrated rule or a drafting prompt that does not reflect it.
Recursion gives the criteria their practical force. Three passes with checks and revisions are different from one generation followed by a grade, because each review can change the next draft. The number of passes needed to converge is therefore diagnostic. It reveals where the relationship between the specification, drafting instructions, and review process needs attention.
Using an LLM as a judge for semantic criteria — and calibrating it honestly
Semantic review depends on calibration against human judgment. A model can evaluate vague claims, stress position, voice consistency, and citation discipline, but its default preferences are not the team’s preferences. An uncalibrated judge evaluates against its own prior. A detailed prompt alone does not show that the judge makes the same decisions as the editorial team.
Calibration starts with examples from the team’s corpus that experts have labeled. The judge scores those examples, and the team computes exact-match agreement and mean absolute error against the human scores. Mismatches then guide iterative changes to the judge’s prompt. Each revision must be evaluated against the labeled examples. Otherwise, a more persuasive explanation from the judge can be mistaken for a more accurate judgment.
The reliability limit is substantial and must remain explicit. Existing LLM-as-judge methods achieve only moderate performance on long-form evaluation, with performance lowest on deep research, including RealDR, and creative writing also among the more challenging domains. A model judge is not a final arbiter. Architecturally, it belongs within a multi-signal evaluation that also includes deterministic results and thresholds for human review.
There is a further risk in encoding taste too broadly. Low entropy, predictable burstiness, and uniform transitions can occur in highly edited, technical, or non-native writing as well as generic AI prose. A gate built around those signals alone can penalize legitimate writing. Calibration requires annotated examples that distinguish a failure from an intentional choice.
What watermarking and AI detection add to the picture — and what they do not solve
Watermarking raises a different question from editorial quality. It concerns who controls the provenance signal. OpenAI announced textGrain on October 5, 2026, for eligible ChatGPT and Codex text output in the EU, with a mandatory default at launch and global API opt-in. The vendor controls that signal. The absence of a public verification interface or detector specification for content teams limits its use as infrastructure they can integrate themselves.
Detection without watermarks instead uses patterns in word choice and transitions that come from a model family, along with stylometric analysis. GPTZero’s 2026 paper, “GPTZero: Robust Detection of LLM-Generated Texts,” describes a hierarchical, multi-task architecture and reports robust detection across domains and languages, including resistance to adversarial paraphrasing through multi-tiered red teaming. A detector’s classification does not establish whether claims are precise or terminology is consistent.
Provenance signals also have their own limits. The DITTO paper from EACL 2026 demonstrates watermark spoofing, in which a malicious model produces text with an authentic-looking watermark from a trusted victim model without access to that model’s key. Watermarks alone are therefore insufficient as a provenance guarantee. They cannot substitute for quality checks either.
A system that shares writing across multiple models and enforces its own criteria produces a different statistical signature from the uniform one found in single-model output. That makes it structurally harder to fingerprint. Detection resistance, however, is a byproduct of architectural diversity and quality enforcement. The editorial task remains to demonstrate compliance with named standards.
How do teams automatically enforce content standards before publishing?
A working implementation places editorial criteria in the developer stack. The versioned voice specification functions as a maintained schema, with the senior editorial lead responsible for its contents. A linter or CLI runs structural checks at generation time and in CI. A separately configured model judge evaluates semantic criteria against the team’s labeled examples. These components perform different jobs and should not be treated as interchangeable quality scores.
The checks form a gated workflow with explicit consequences. Deterministic violations can be identified without a model call, while semantic findings proceed through the calibrated review process. The orchestration layer routes findings back to the draft agent for revision. Per-criterion thresholds define what passes, what triggers human review, and what blocks merge. This creates a risk-tiered decision process rather than requiring humans to inspect every line indiscriminately.
The available tools are best understood by their roles. The agent-style tool shows how deterministic structural checking works, while a calibrated model judge checks properties that need more than pattern matching. GPTZero addresses detection rather than compliance with a team’s voice specification. None of those roles replaces orchestration, ownership, or release thresholds. Governance comes from their defined responsibilities within the workflow.
Humans set the criteria and decide when to escalate before generation begins. The system then enforces those decisions on every pass, returning exceptions for judgment rather than outsourcing routine correction to editors. Governance asks “what criteria does good writing satisfy, and how does a system enforce them? That question gives engineering a specification it can implement.