GRPO Reward Shaping for Language Models
How to give GRPO's scalar reward finer, fairer credit.
Soren Halvgaard
12 stories
How to give GRPO's scalar reward finer, fairer credit.
Production writing APIs need routing, revision loops, and voice checks.
RAG handles facts that change; fine-tuning shapes how models write.
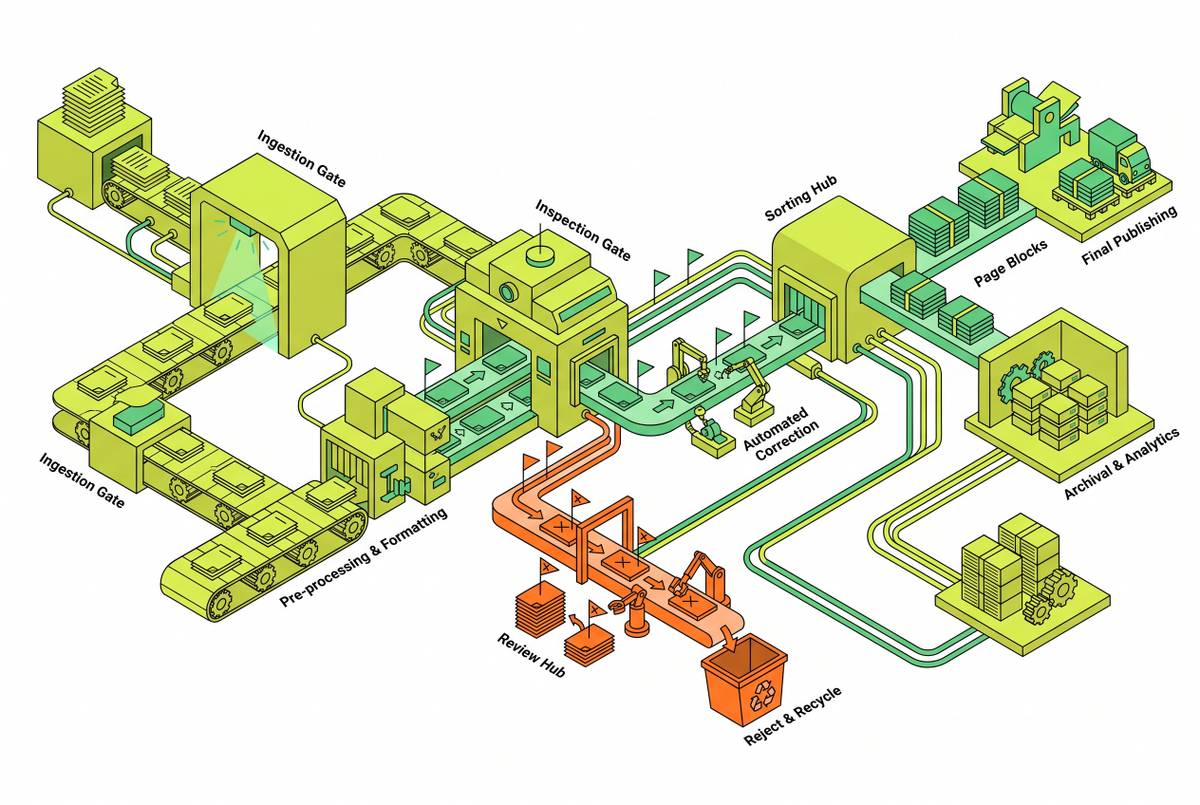
Release notes need structured pipeline stages, not just a better writing model.
Harnesses enforce voice and accuracy through architecture, not just prompts.
Editors need clear rules for using AI detection as one signal in decisions, not as final judgment.
Readability formulas miss the deeper qualities that actually make prose effective.
Structured pipelines catch AI content errors that spot-checks miss.
Multi-model pipelines defeat detectors trained on single-model fingerprints.
Technical readers demand precision, and single models can't deliver it reliably.
Training on the internet makes brand voice impossible without a system around the model.
Single-pass writing has no way to stop, so iterative loops need criteria.